Research / HCII 2026
Visible ReasoningUser-Facing Decision Transparency for Generative AI Systems
Artificial Intelligence in HCI · HCII 2026 · Lecture Notes in Computer Science 16745 · pp. 3–21 · Springer, Cham
Abstract
Across multiple waves of computing, public trust in new technology has followed the emergence of governance mechanisms that made dominant risks legible and manageable. Generative AI shifts this pattern: these systems synthesize across heterogeneous sources, and users increasingly experience them as reasoning systems. The central question changes from "did it perform correctly?" to "can we trust how it arrived at its conclusion?"
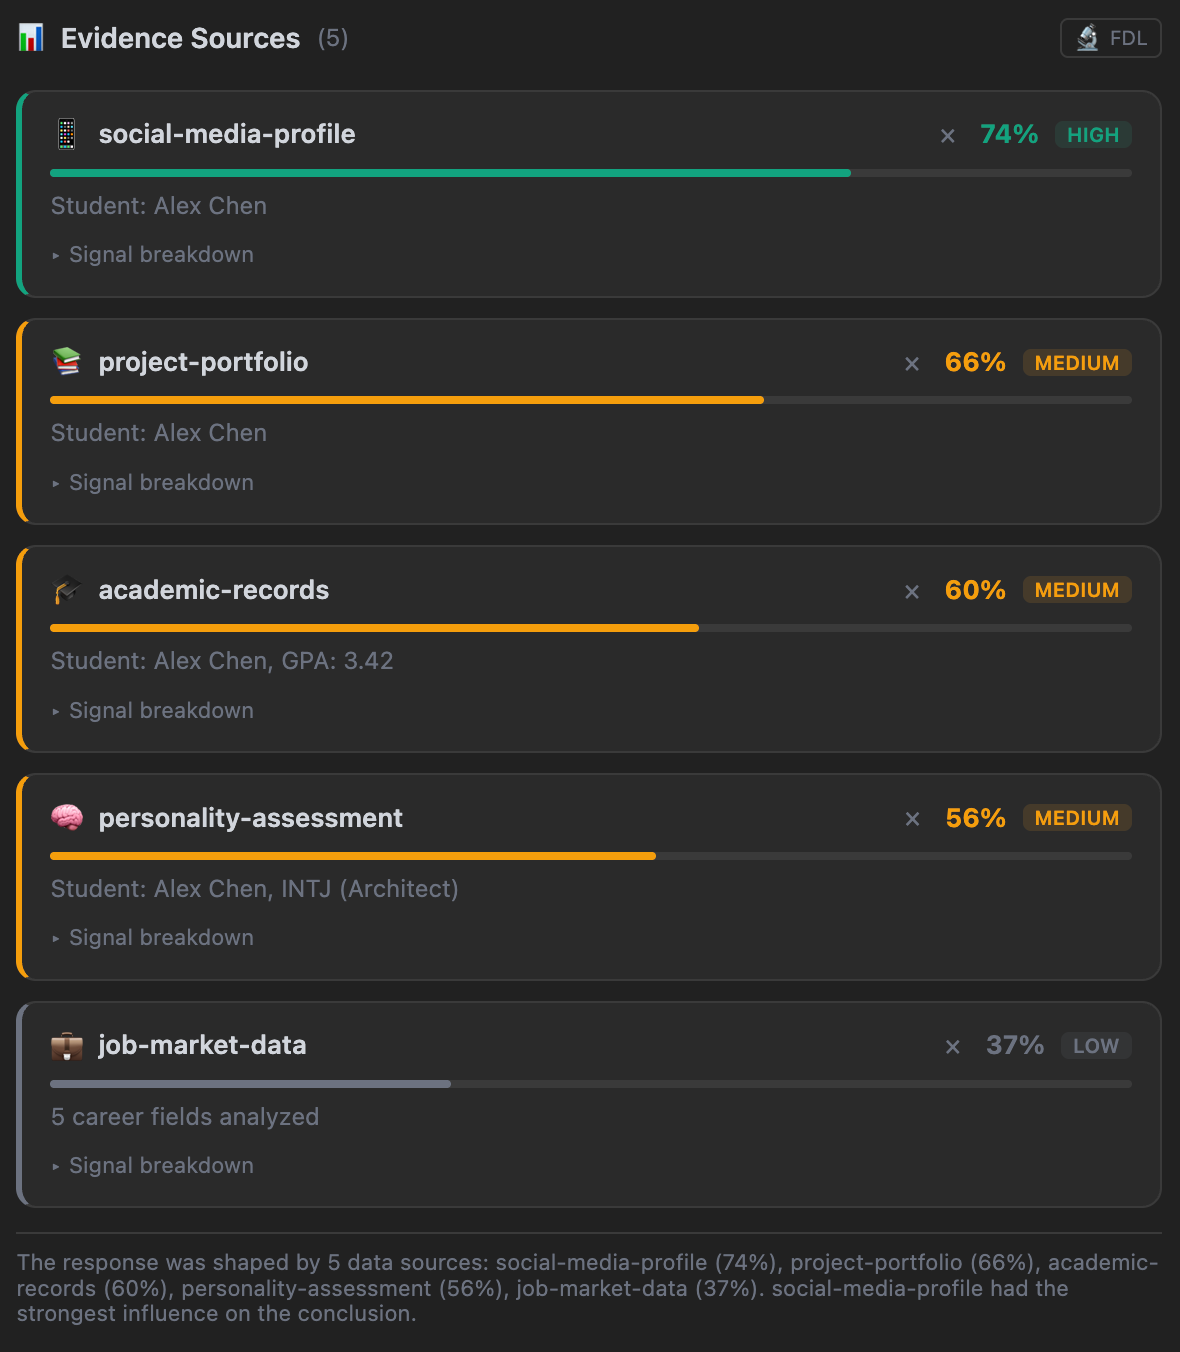
This paper introduces Filtered Decision Logs (FDLs), a user-facing transparency mechanism that makes decision formation visible without exposing raw chain-of-thought. FDLs pair each response with (i) a concise decision rationale, (ii) influence-ordered supporting data points derived from tool outputs, and (iii) relevance indicators showing which sources most shaped the conclusion. To operationalize evidence selection, we propose a trace-based method that reconstructs observability telemetry into a provenance tree and ranks evidence using four deterministic semantic and structural signals - Final Answer Similarity, Average Relevancy, Persistence, and Structural Proximity - combined via adaptive weighted scoring. We demonstrate FDLs across three domains: career advising (5 tools), investment analysis (4 tools), and travel planning (4 tools). In a formative evaluation with 50 participants (25 students, 25 working professionals in AI development), 92% rated the influence-ranked evidence as helpful for understanding and trusting the system's recommendation. Counterfactual tool-removal experiments confirm that removing the top-ranked source changes the answer more than removing a low-ranked source, validating that the ranking tracks decision dependence. We conclude that evidence-ranked transparency helps users identify misleading signals and missing context, enabling more confident acceptance, correction, or re-run of system decisions.
The idea, in practice
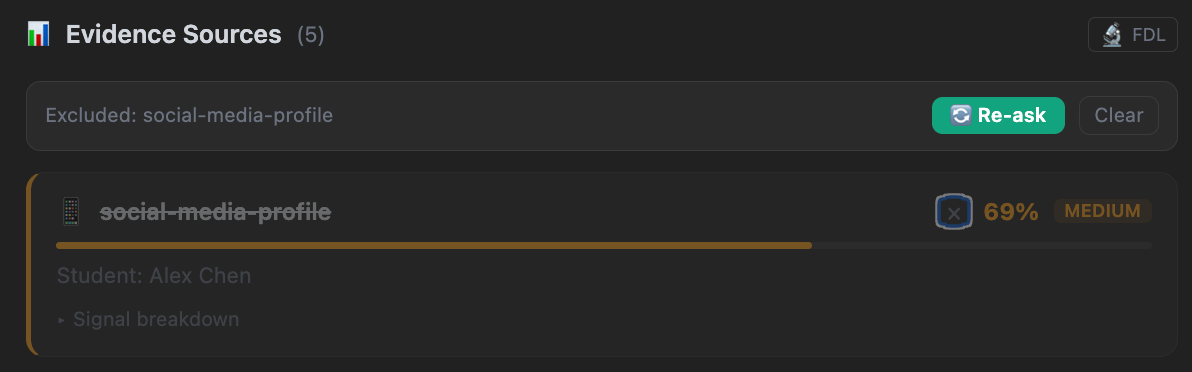
Show the recorded evidence behind an agent’s answer, then let people exclude a source and ask again.
- Pair an answer with a concise rationale and ranked evidence drawn from recorded tool outputs.
- Combine semantic and structural signals to rank evidence. Treat ranking scores as alignment signals rather than causal percentages.
- Let people exclude a source and ask again, then examine the changed answer. The paper also reports counterfactual tool-removal checks and a formative evaluation.
Try the idea
Inspect a recommendation, remove an evidence source, and compare a fresh answer.
This is a later illustrative implementation using AgentFootprint and FootPrint. It does not reproduce the original paper’s experiments or participant study. Sample replies are scripted; live replies come from Anthropic.
The evidence desk
Focused playgroundInspect a recommendation and its recorded evidence, exclude a source, and compare another run. Keep the exploration trail and revisit captured states.
Start with the scripted sample at no API cost. Live Anthropic mode uses your own key. Replay restores captured states; it makes no API call.
Runtime: AgentFootprint 7.7.0 · FootPrint 9.11.0. Playground source and build instructions. For the larger reference examples, see the run guide or full application gallery.
Scope & limitations
The paper’s 50-participant evaluation was formative. The original experiment stack used Claude 3 Sonnet and Amazon Titan embeddings. The playground here uses a later library implementation, synthetic evidence and a deterministic mock embedder; its output is not a reproduction of the study or its scores.
Cite the paper
Cite the published HCII chapter. The arXiv link provides free access to the original pre-review author manuscript.
@inproceedings{anbalagan2026visible,
  author = {Anbalagan, Sanjay Krishna and Nie, Xinrui and Kommalapati, Anughna and Kanamarlapudi, Vijay Kumar and Radhakrishnan, Sreekanth and Zhao, Xiaodan and Mohan, Umesh},
  title = {Visible Reasoning: User-Facing Decision Transparency for Generative {AI} Systems},
  booktitle = {Artificial Intelligence in HCI},
  series = {Lecture Notes in Computer Science},
  volume = {16745},
  pages = {3--21},
  year = {2026},
  publisher = {Springer Nature Switzerland},
  address = {Cham},
  doi = {10.1007/978-3-032-30849-8_1},
  url = {https://doi.org/10.1007/978-3-032-30849-8_1},
  note = {Author manuscript: https://arxiv.org/abs/2610.35483}
}